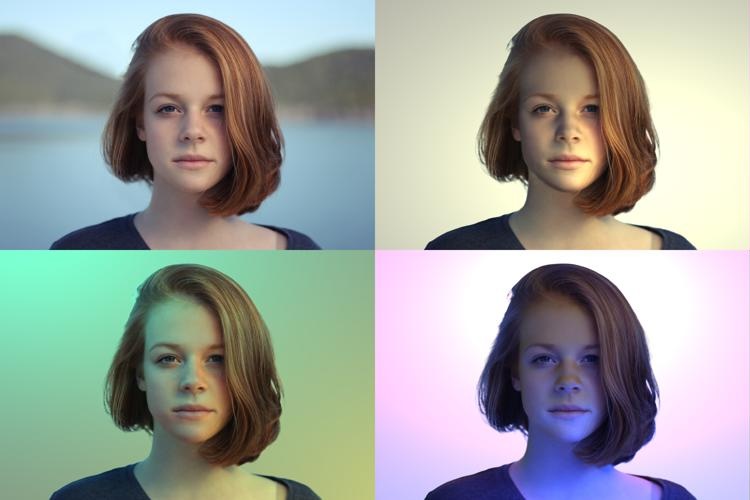I develop large-scale generative and multimodal systems for image editing and generation, building on diffusion and transformer-based foundation models. My work spans problem formulation, model design, large-scale training, rigorous evaluation for production deployment.
Over the past few years, I have developed and shipped generative AI systems for image editing and generation that are used by millions of users and have helped secure contracts worth seven figures in annual revenue.
I currently lead the Image Research team at
Jasper, developing state-of-the-art generative and multimodal models. Previously, I was
a Research Scientist at Stability AI.
I hold a PhD in Computer Vision and Machine Learning from
Inria.
Research work that I directly contributed to, spanning research, code, method development, and training at scale.
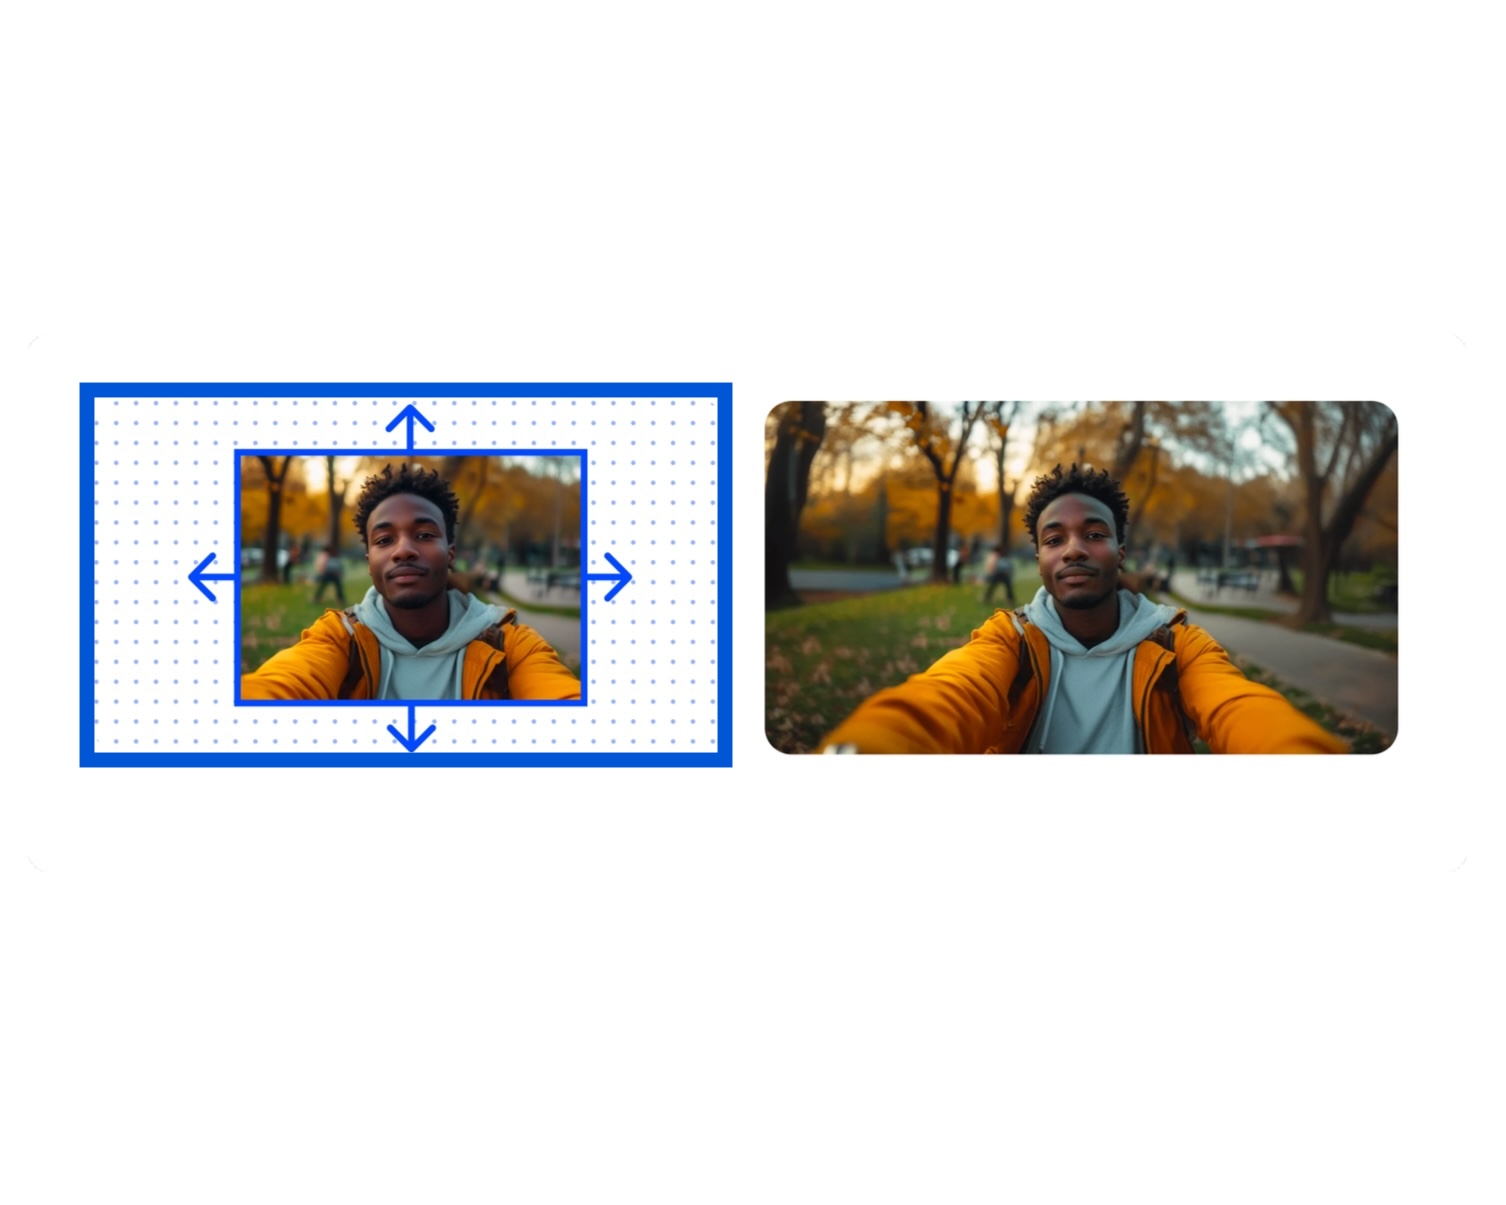
Image expansion (Uncrop)
An outpainting system that extends images beyond their borders
with coherent results. Built on and fine-tuned from
Flux
to improve generation quality, reduce hallucinations, and better
match user preferences with a distilled, lower-latency variant
for faster inference.
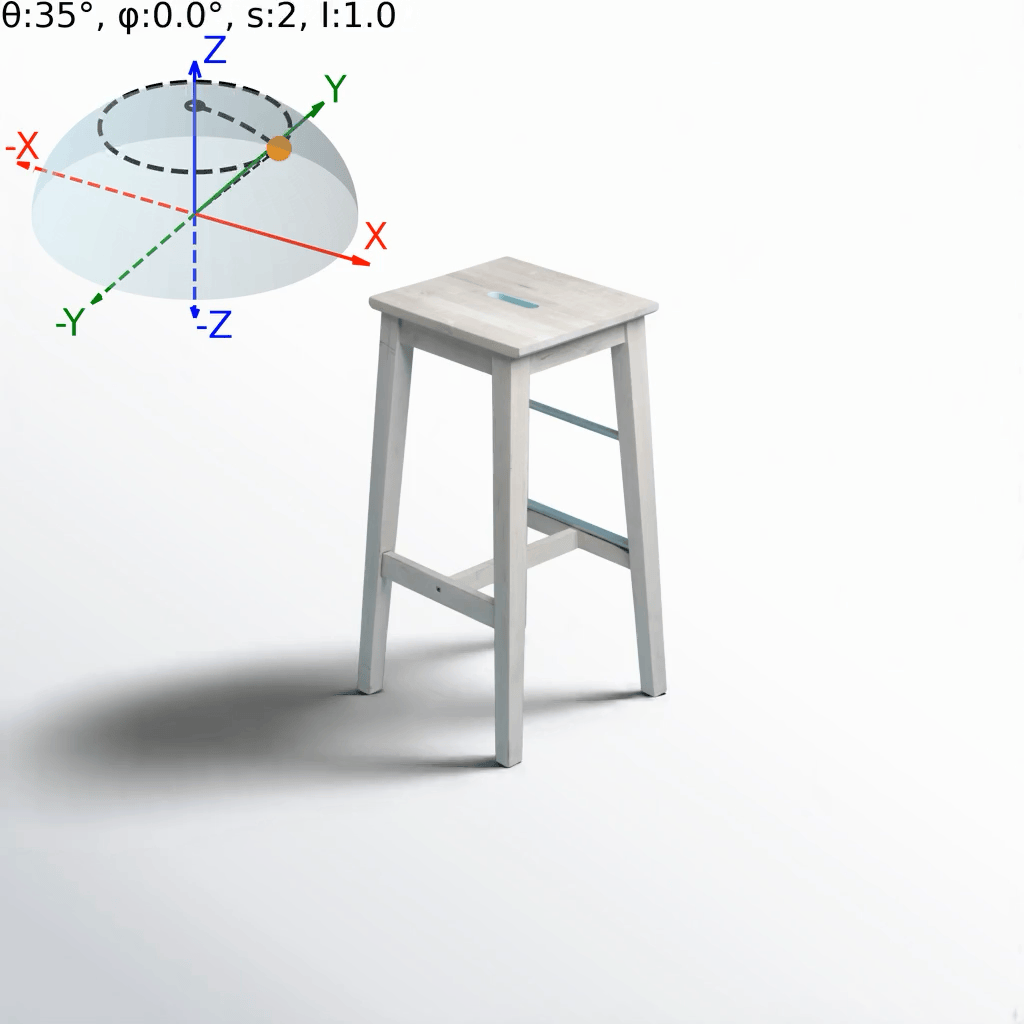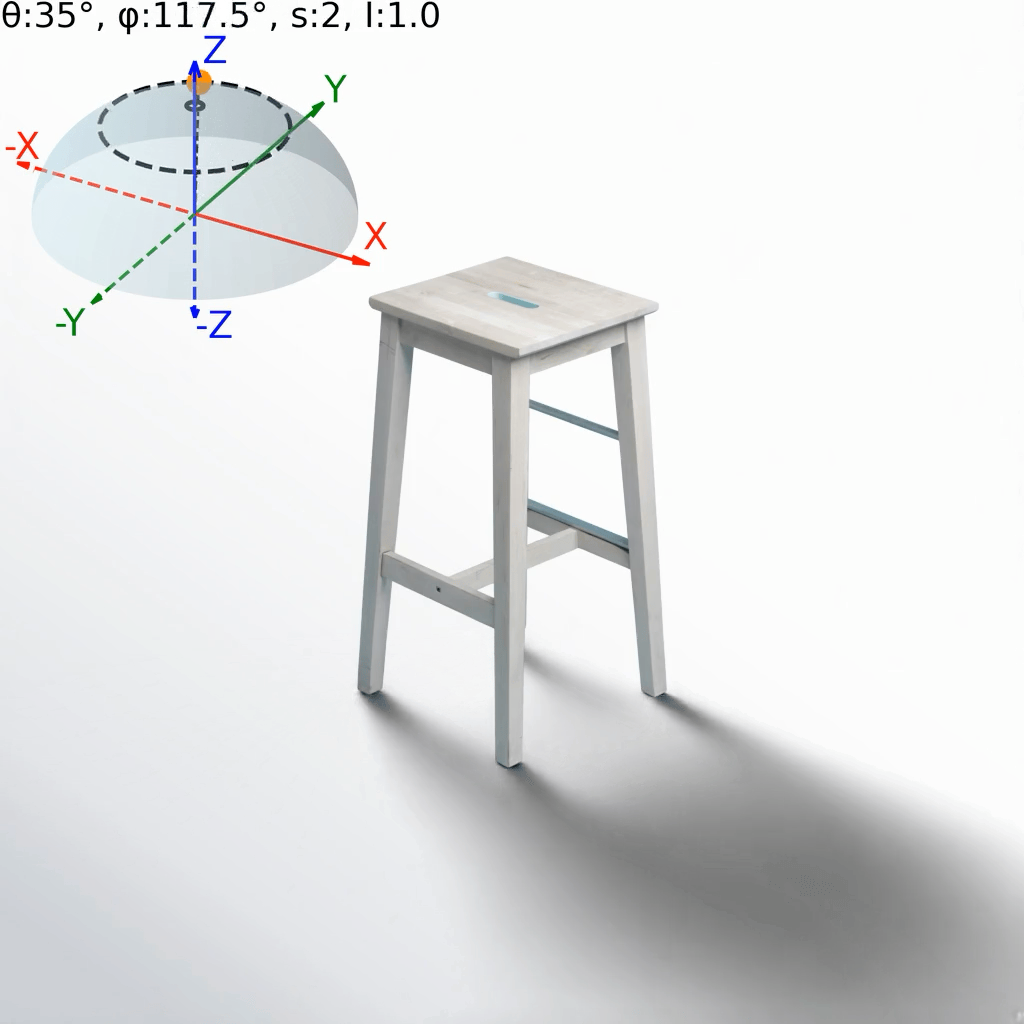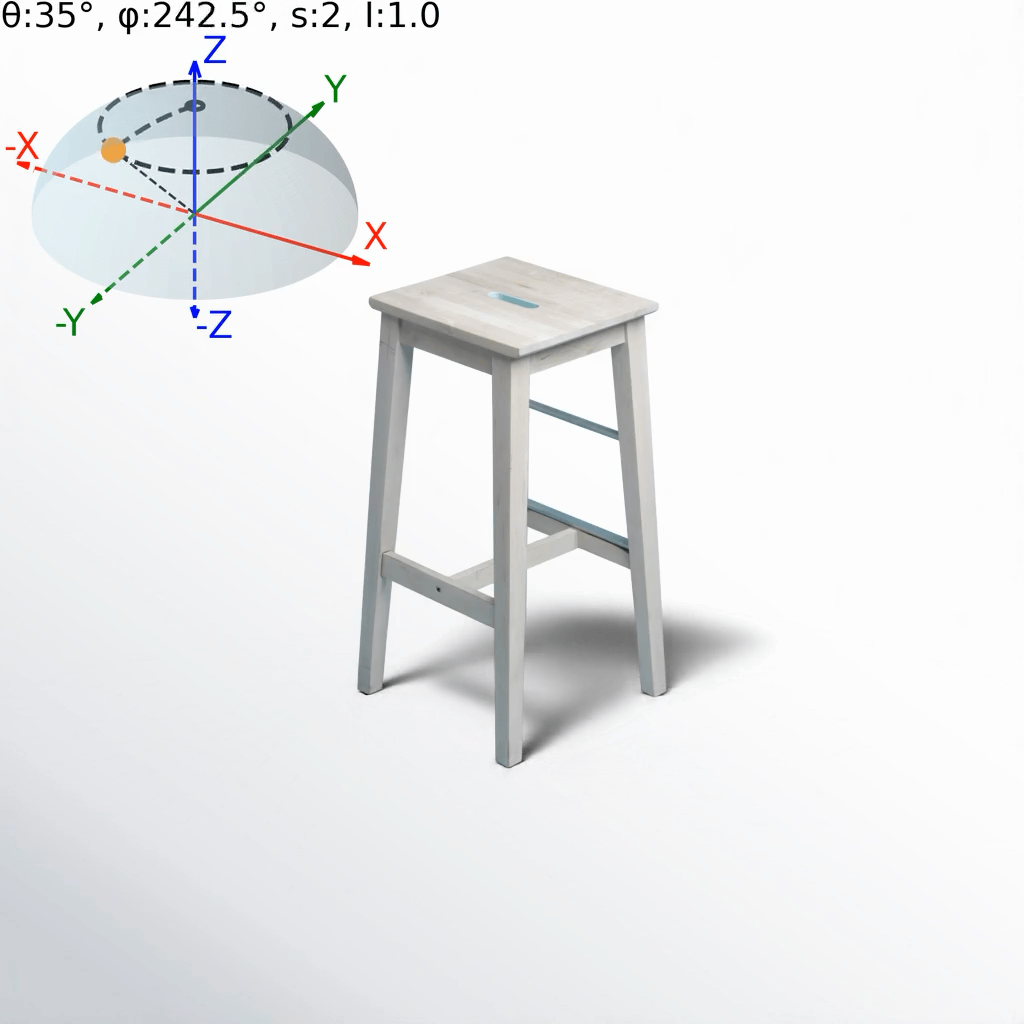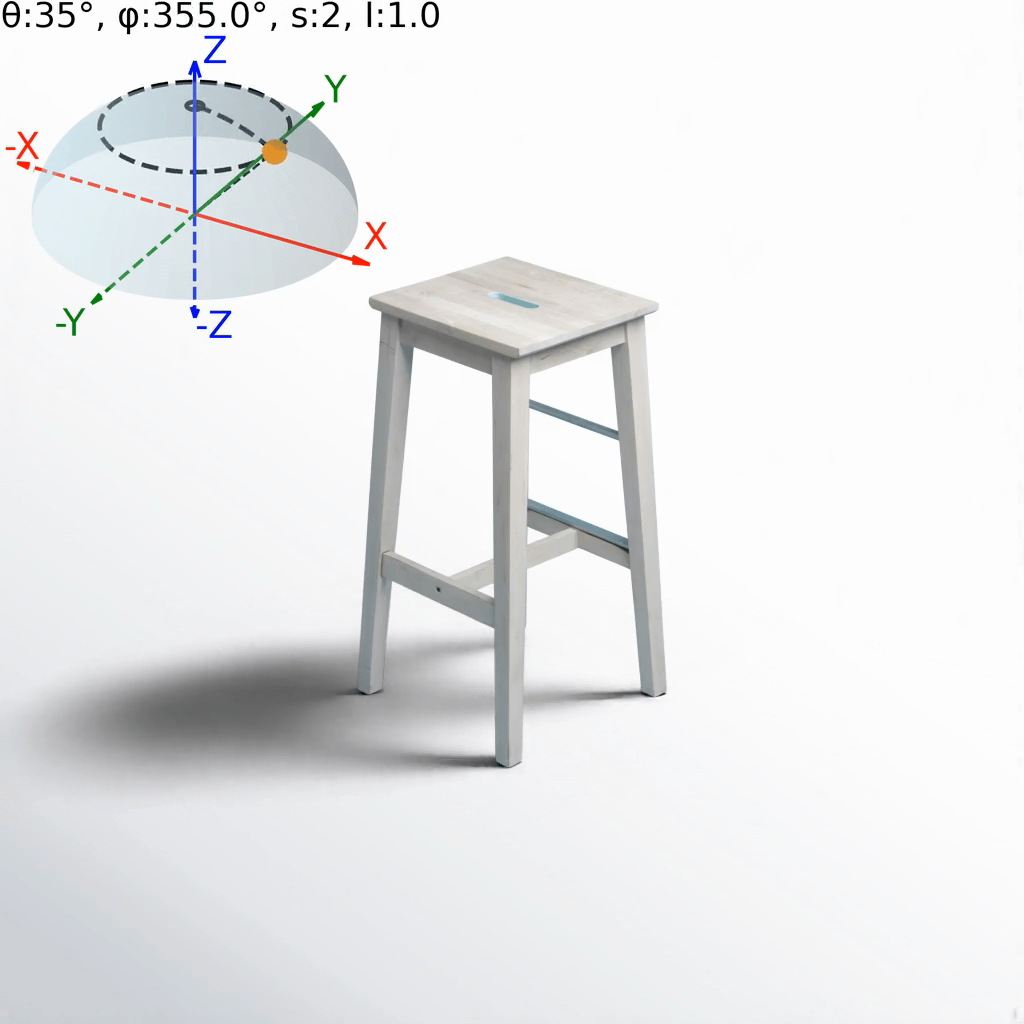
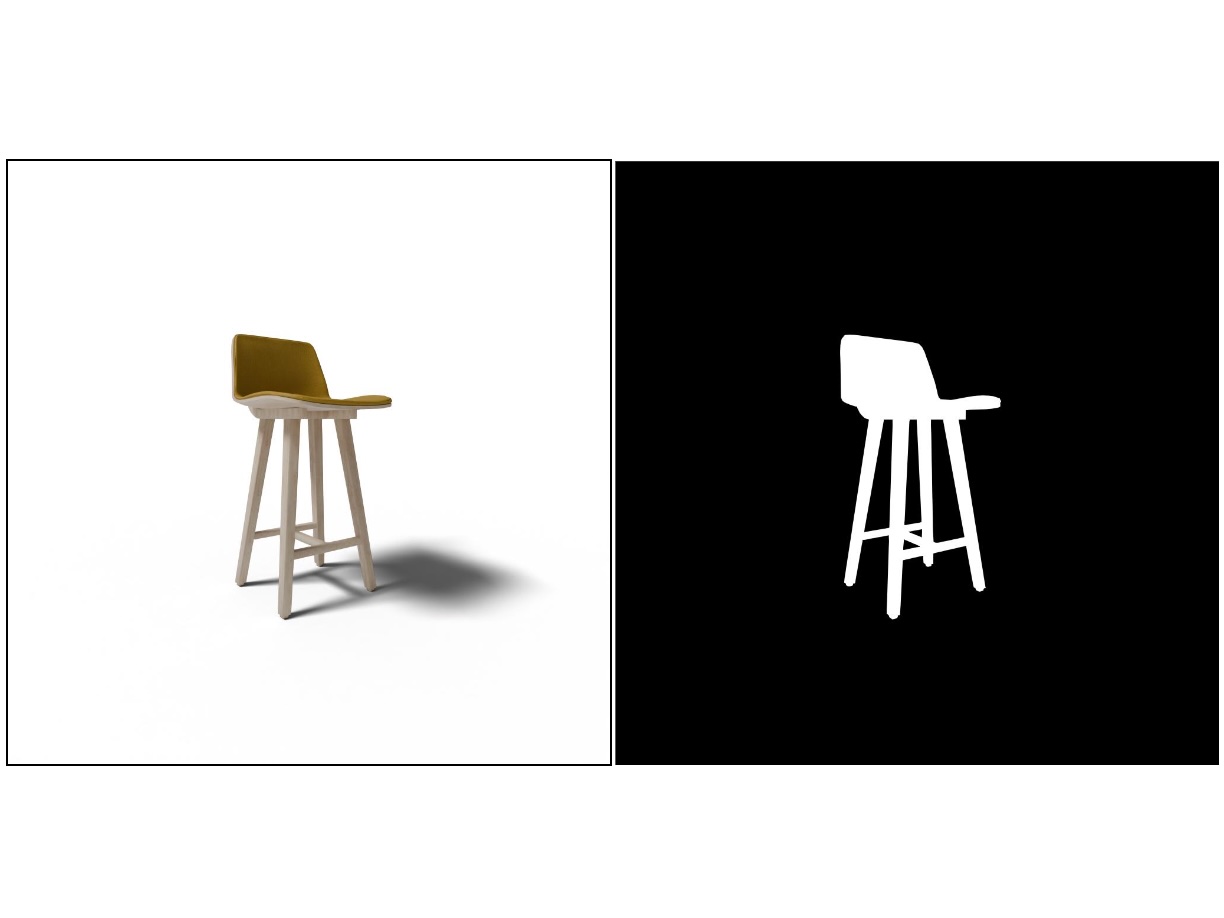
Proposed a method for controllable shadow generation in product
photography, enabling users to control shadow direction, softness,
and intensity. I also created a public benchmark from scratch to
evaluate the quality and controllability of generated shadows.
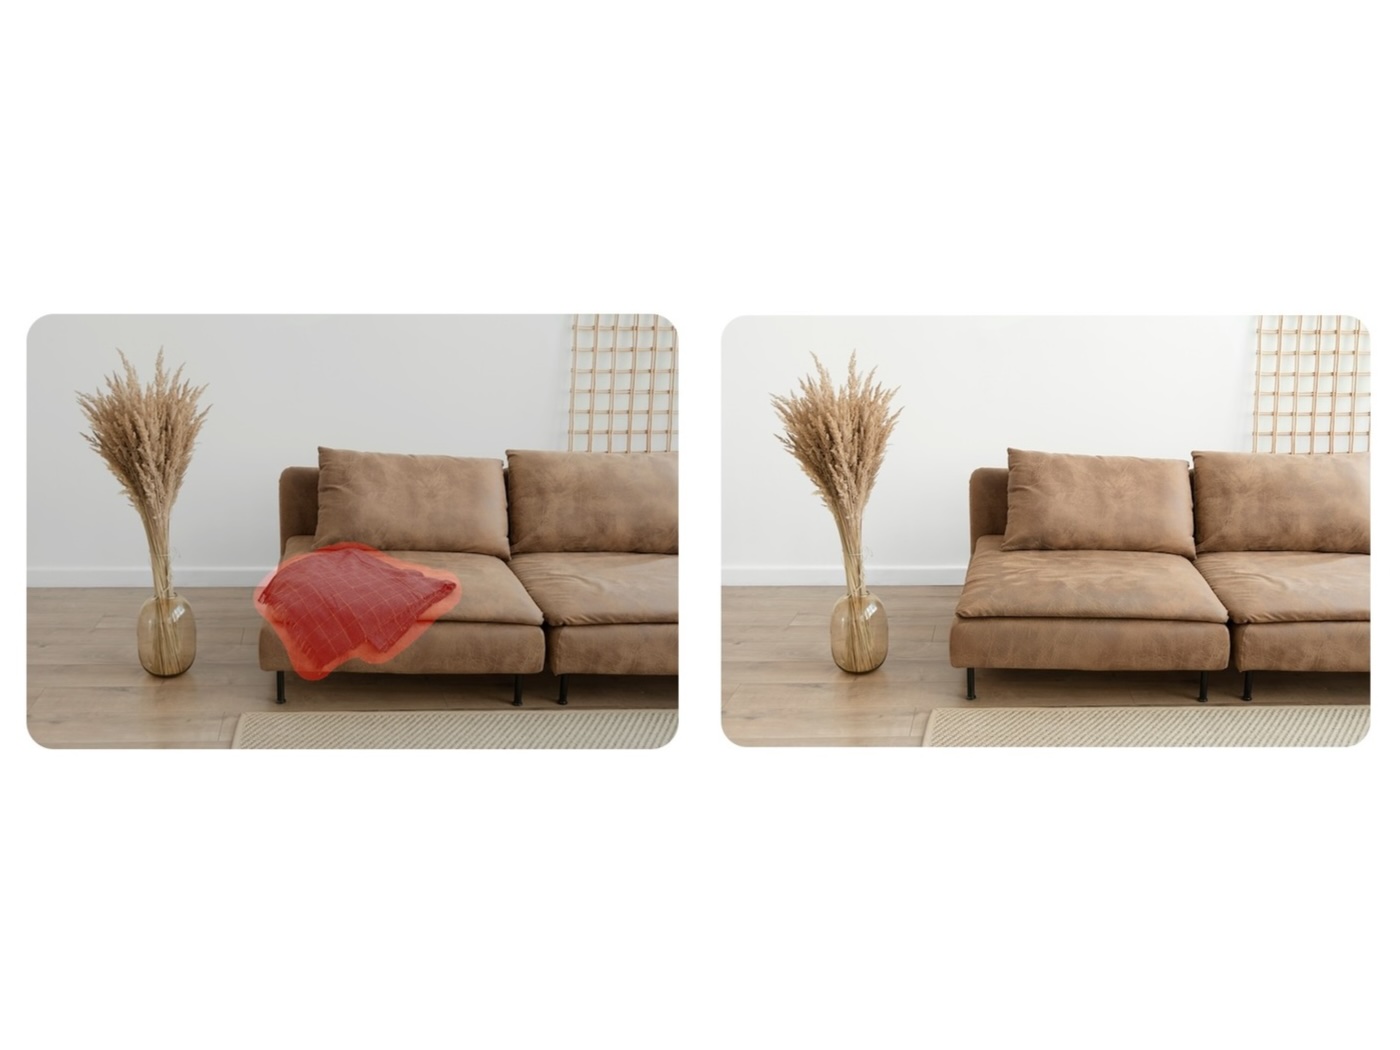
Direct application of our
Latent Bridge Matching
approach (ICCV 2025) for generative object removal, producing
high-quality results in near real time. Extensively fine-tuned
on large-scale datasets for robust, production-ready performance.
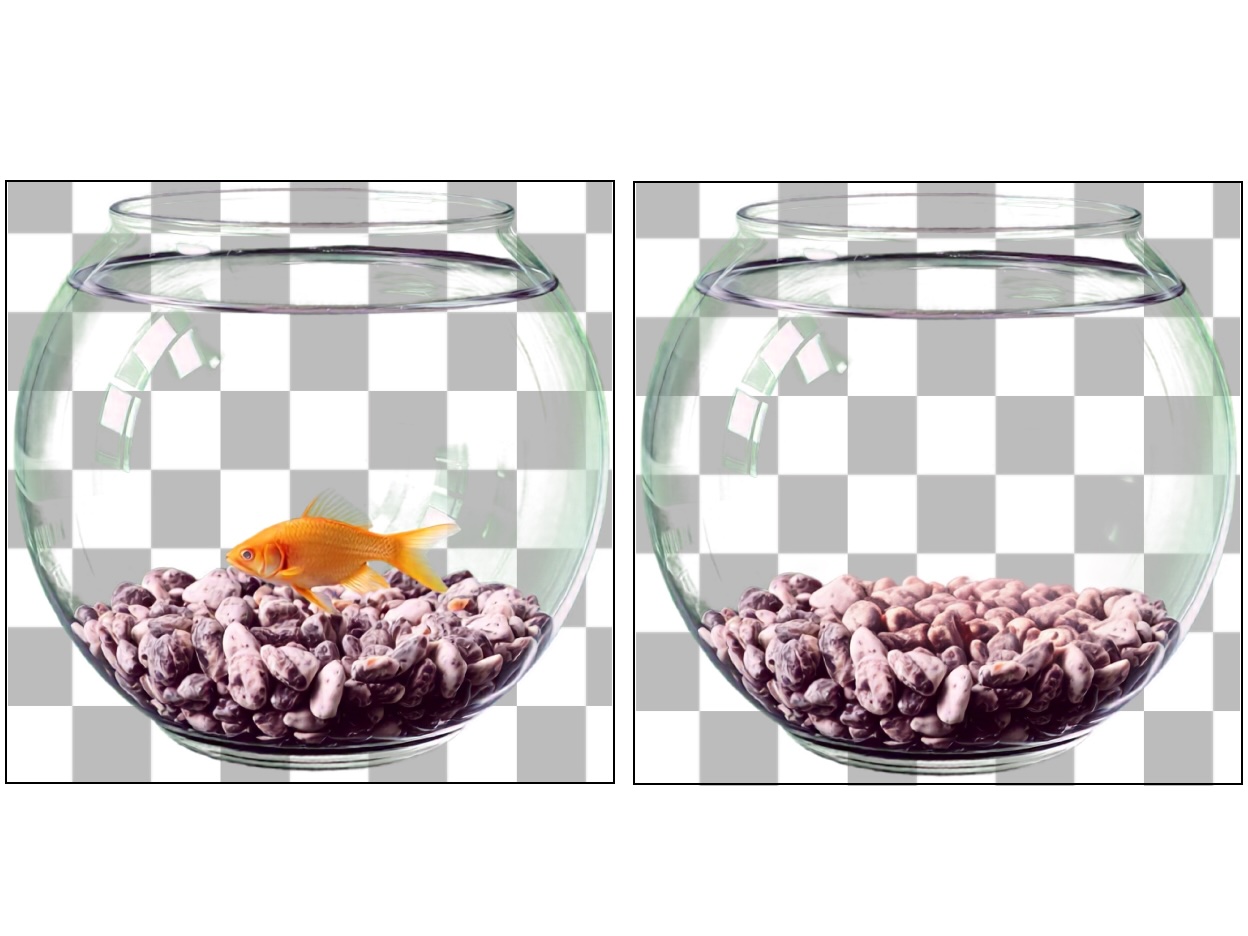
Diffusion-based editing with a custom RGBA variational
autoencoder (VAE) that jointly models transparency alongside
standard color channels. This native RGBA support unlocks
advanced, controllable workflows for design and content
creation.
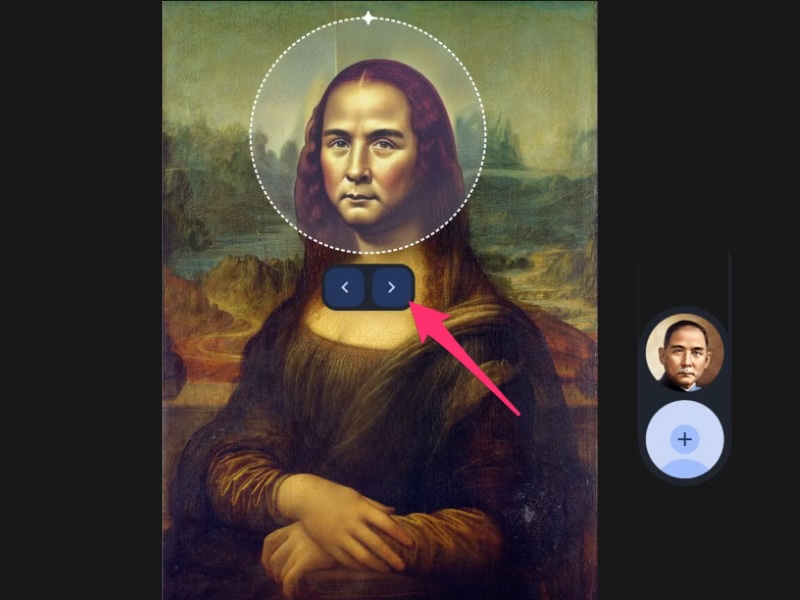
Built a rendering pipeline from scratch on top of
Blender to generate
perfectly annotated, large-scale datasets for training
multimodal generative models. It powers the training of several
of our models, including object removal, relighting, and shadow
and reflection prediction.
Generative relighting of images and objects in real time, with
interactive control over the number of lights and their
properties, including color, intensity, and position. This tool went viral on various social media platforms with millions of views and likes.
Owned the end-to-end development of multimodal, transformer, and
diffusion-based image editing systems, from model design and
training to evaluation and production, powering features used by
millions of users.
Developed object detection models trained entirely on synthetic
data from game-engine rendering and simulation pipelines,
improving robustness under domain shift. The work supported an
Inria-incubated startup that went on to raise €2.5M in seed
funding.